
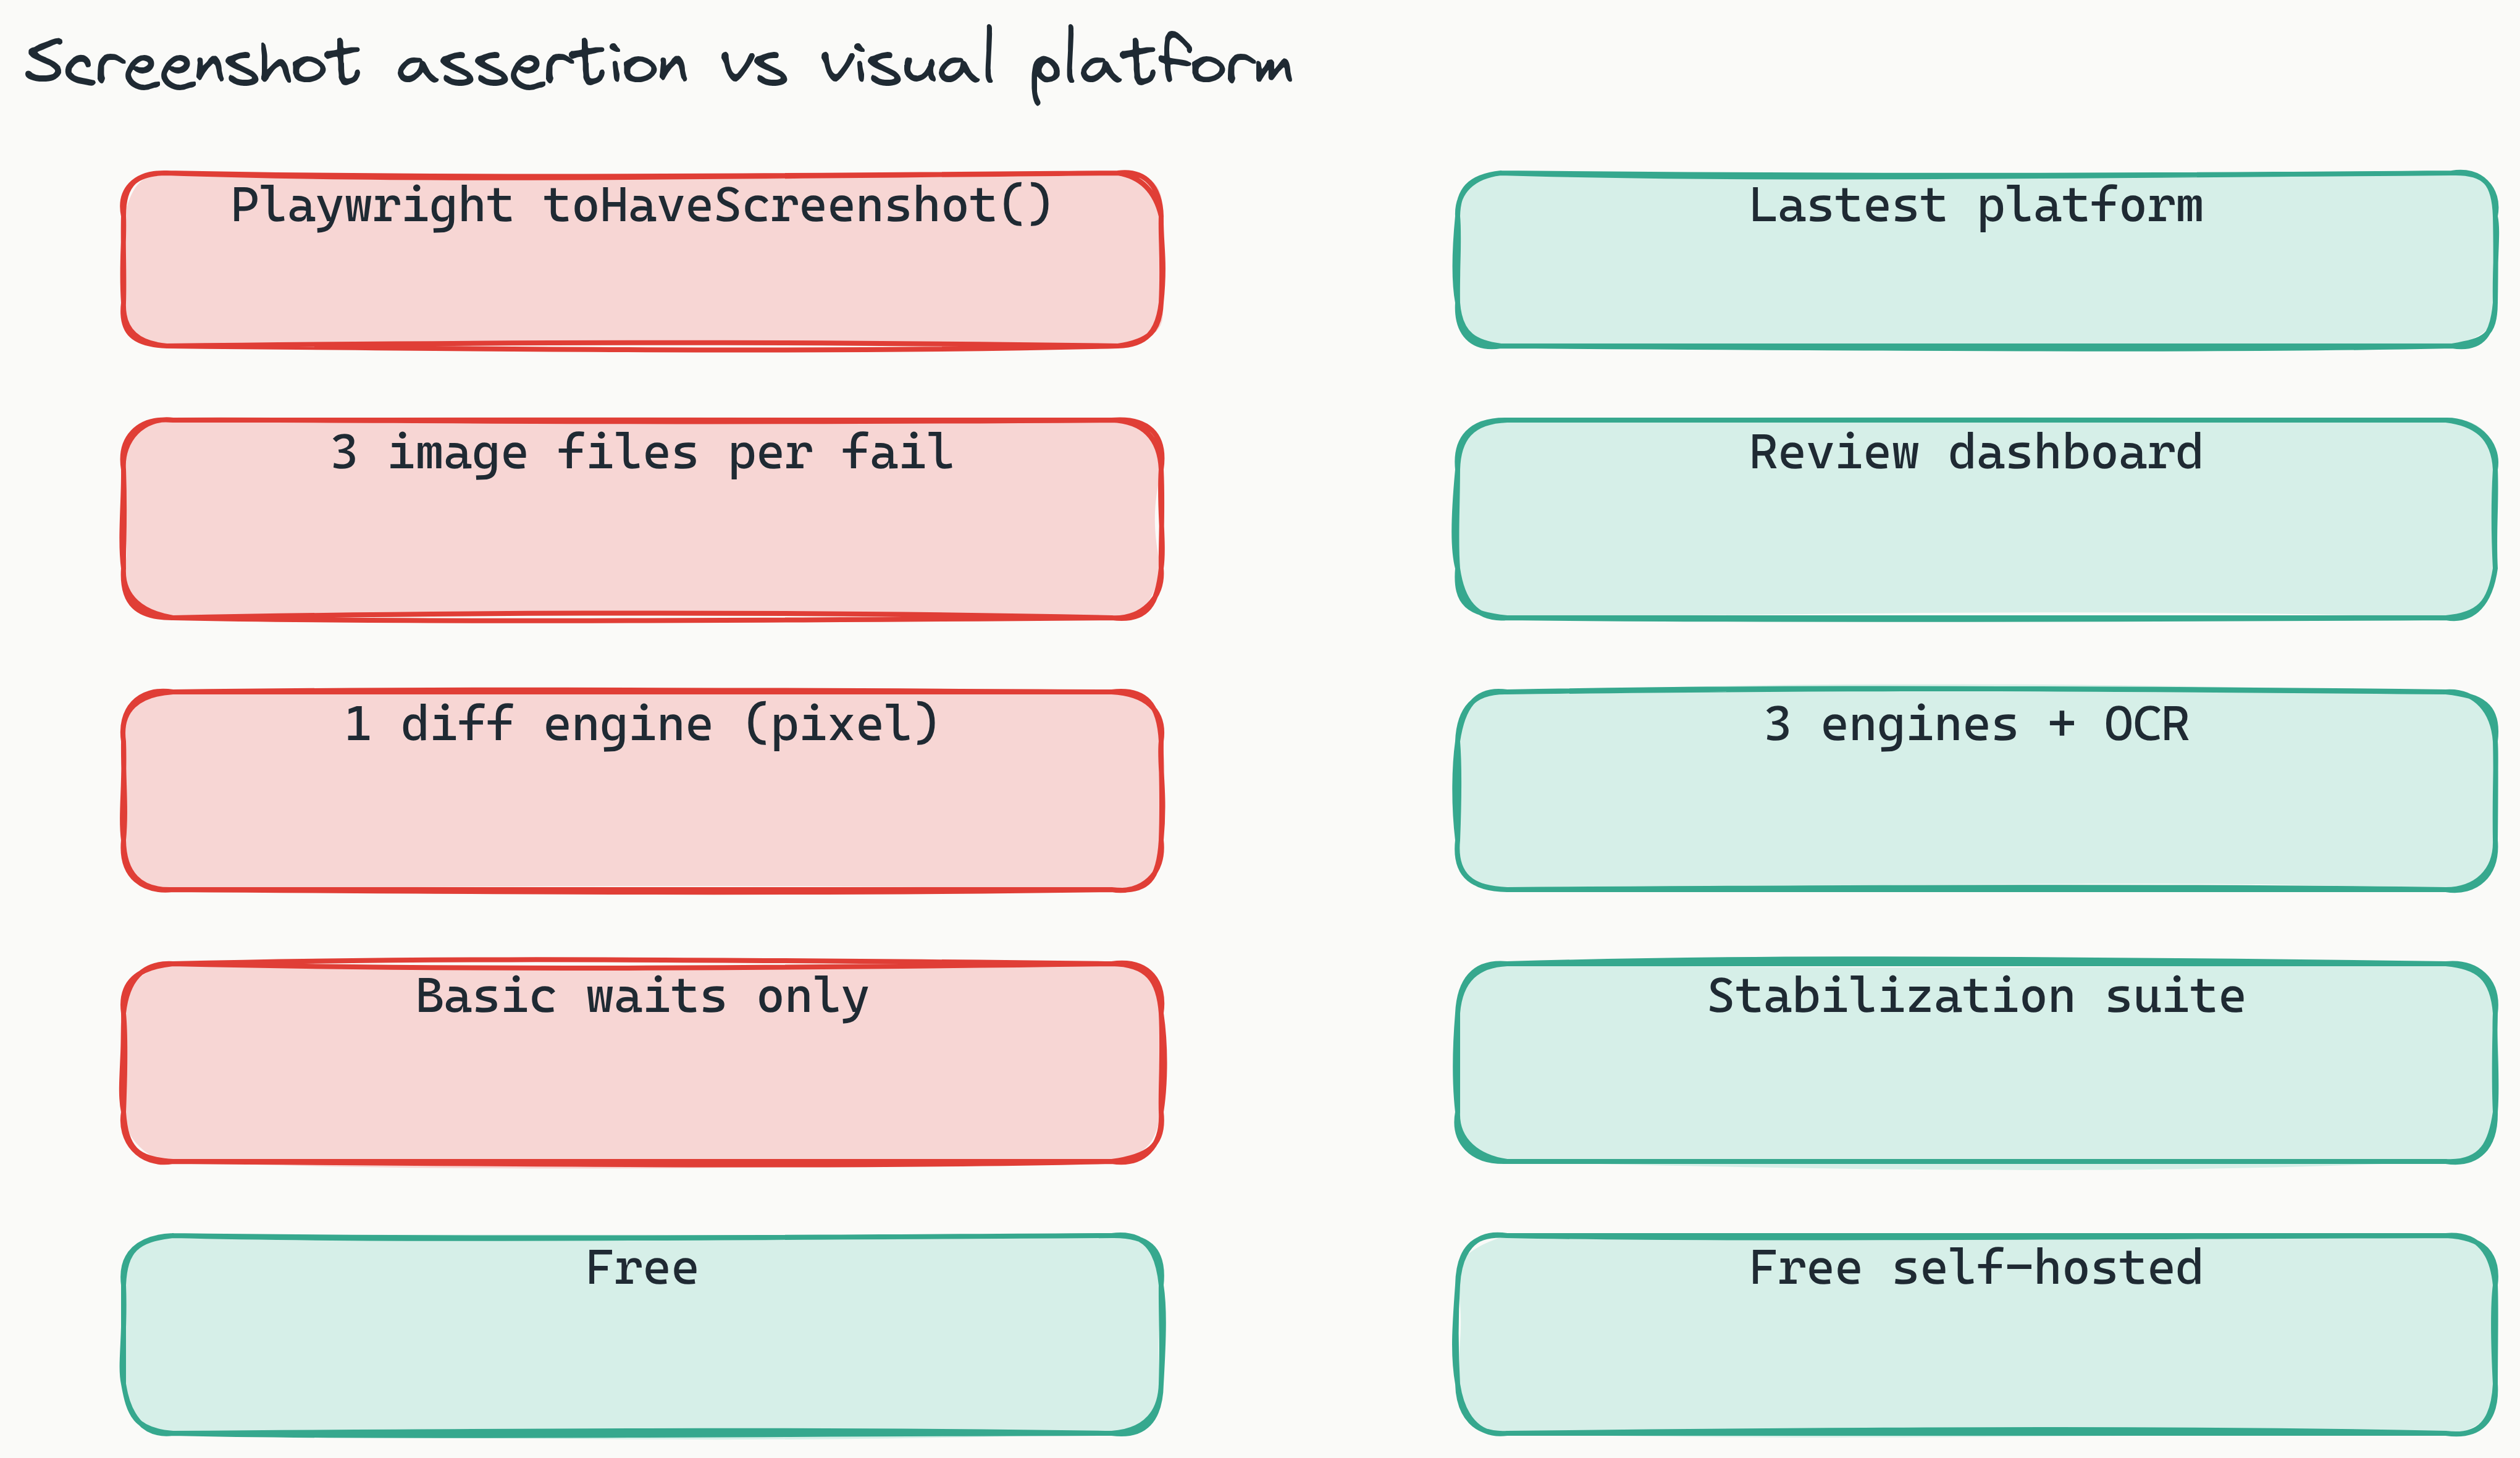
Playwright's expect(page).toHaveScreenshot() is a solid starting point. Built-in, no dependencies, cross-browser. But it's a screenshot assertion, not a visual testing platform.
What's Missing
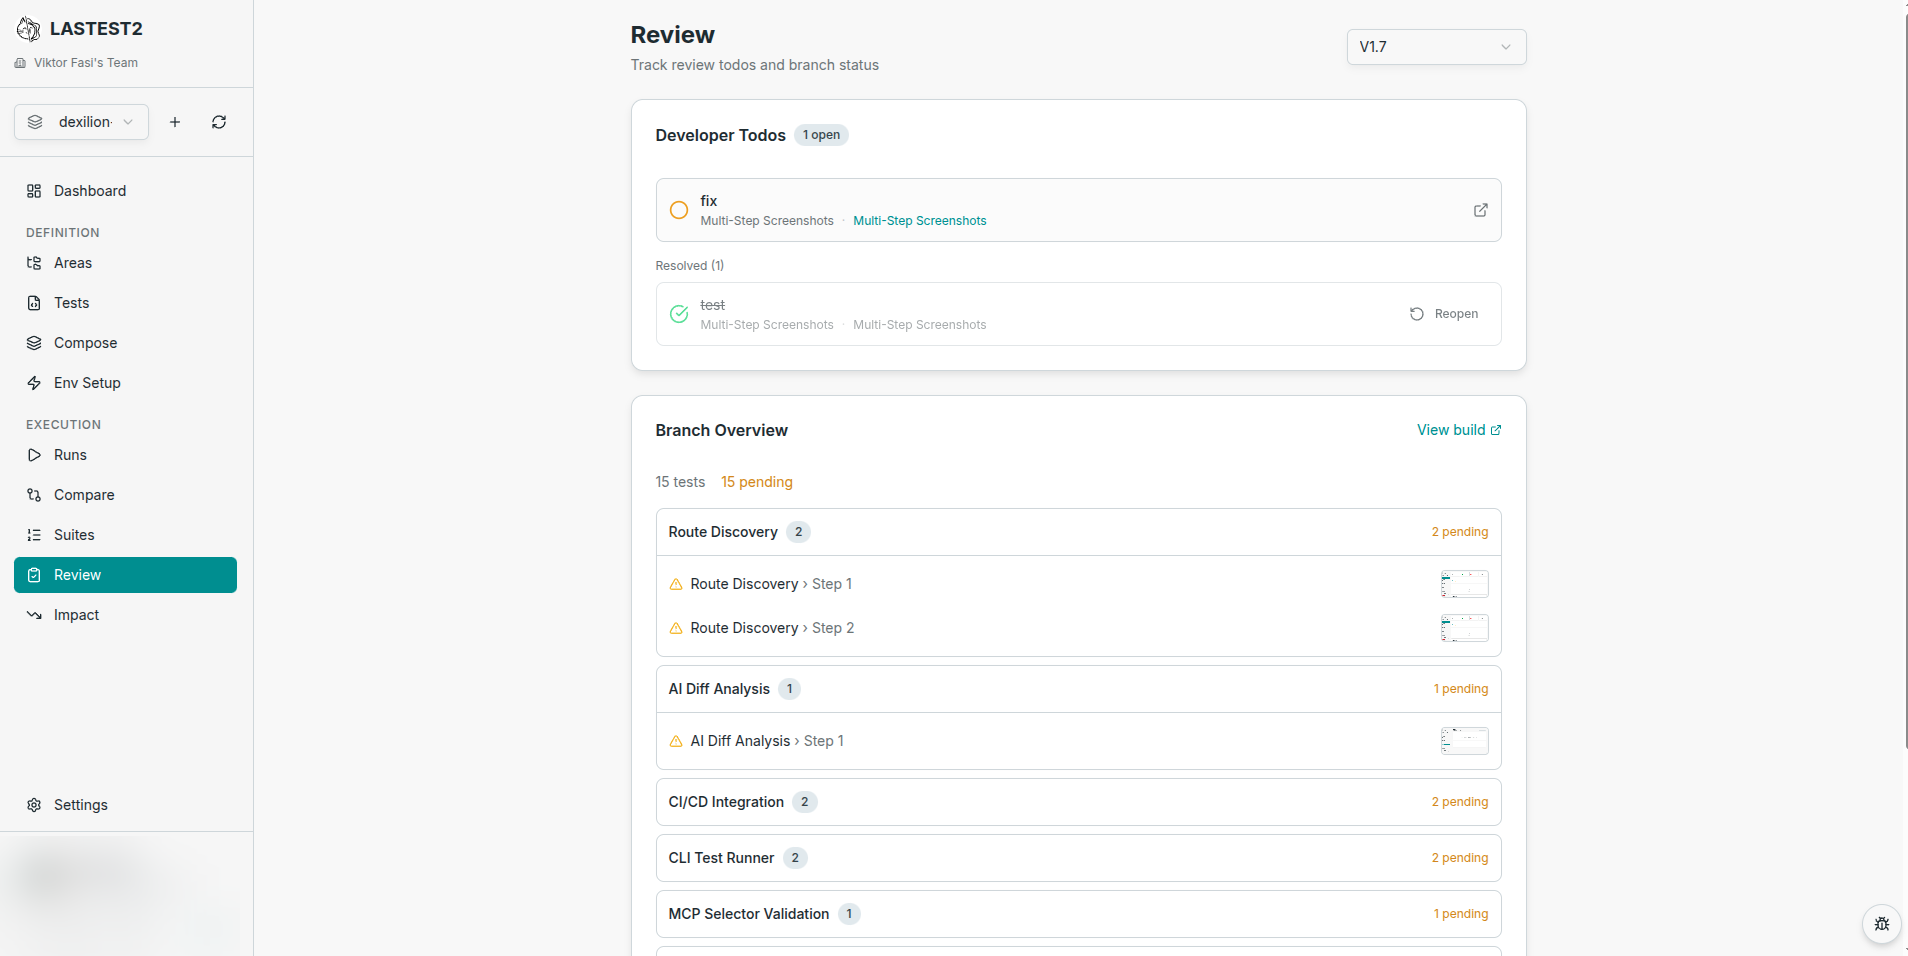
1. No Review Dashboard
Failed tests produce three image files in test-results. For 50 failures after a CSS refactor, that's unusable. You need a dashboard showing all diffs side-by-side with approve/reject.
2. No Team Collaboration
Baselines are files in your repo. No approval workflow - whoever runs --update-snapshots decides the baseline.
3. Single Diff Algorithm
Pixel-by-pixel comparison - fast but prone to false positives from font rendering and anti-aliasing. You need SSIM for structural comparison, Butteraugli for perceptual diffs, and OCR-aware text handling.
4. No AI Test Generation
codegen records one flow at a time. For comprehensive coverage, you need AI that generates your entire suite.
5. No Stabilization
Only waitForLoadState and waitForSelector. Dynamic apps need timestamp freezing, random seeding, third-party blocking, auto-masking, and burst capture.
6. Baseline Bloat
100 tests × 3 browsers × 2 OS = 600 PNG files in your repo. Binary commits bloat git history.
The Gap in Practice
A developer refactors Card used on 30 pages. 30 tests fail.
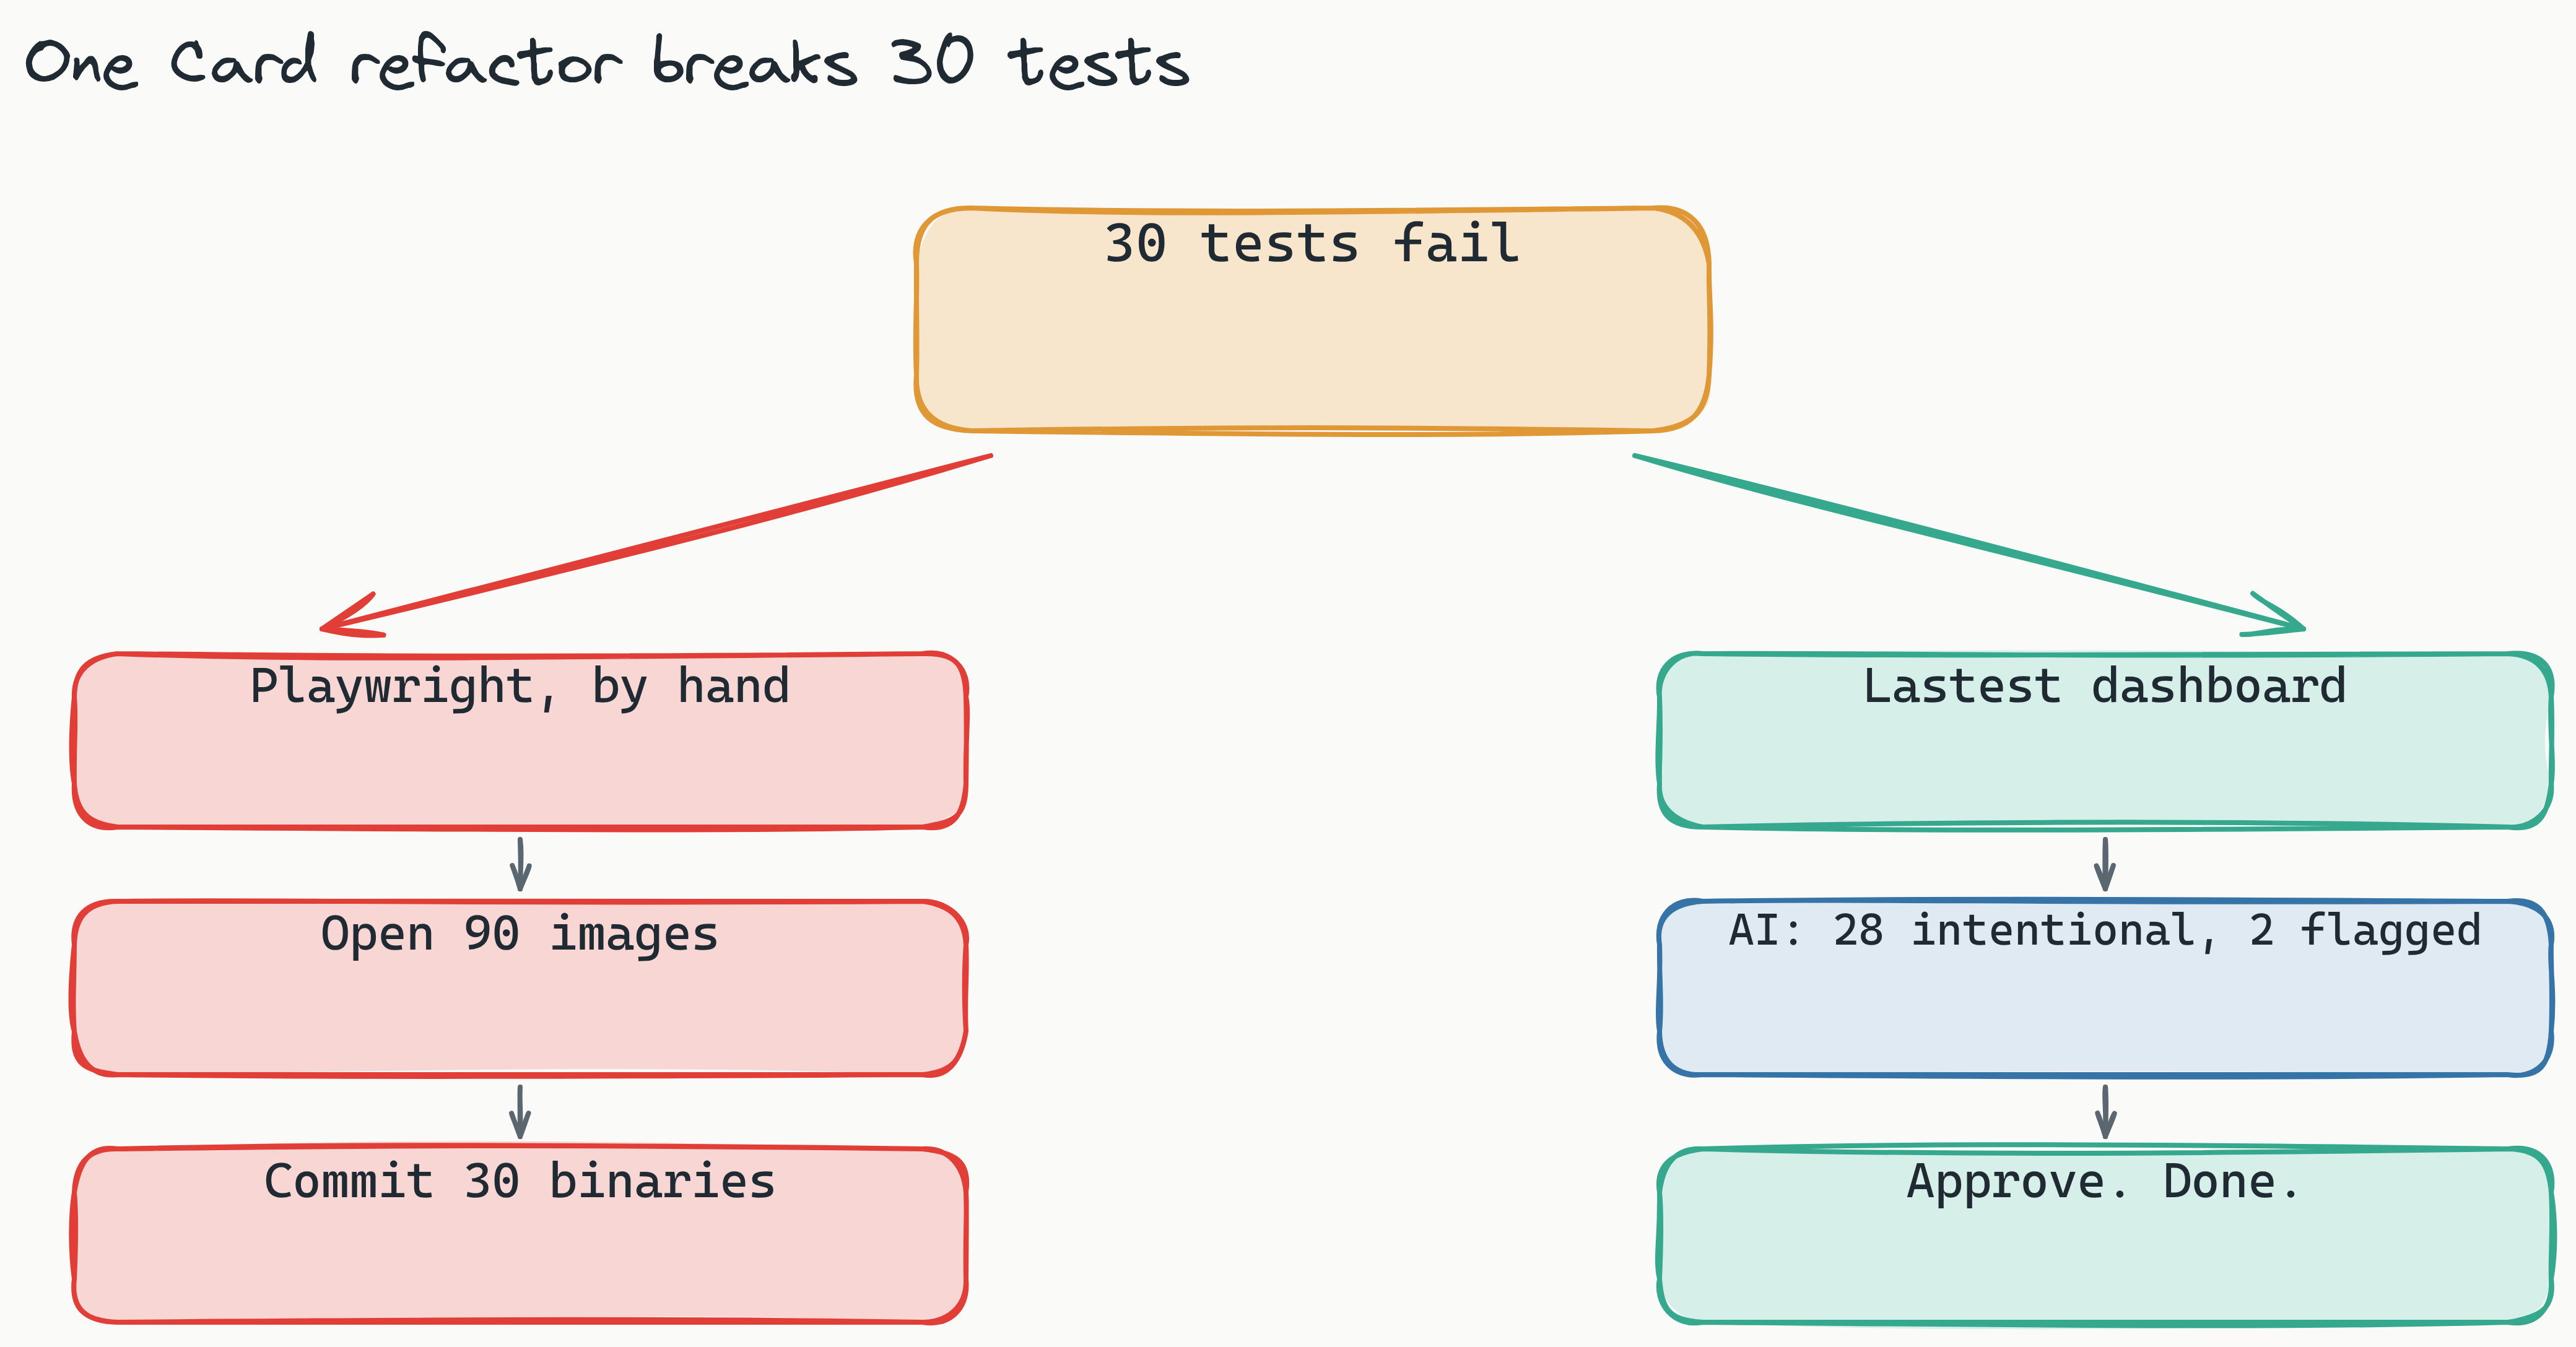
- Playwright: Open 90 images individually. Compare manually. Commit 30 binaries.
- Lastest: Dashboard shows all diffs. AI classifies 28 as intentional, flags 2 as unintended. Approve. Done.
Summary
| Capability | Playwright | Lastest |
|---|---|---|
| Screenshot comparison | Yes | Yes |
| Review dashboard | No | Yes |
| Team approval | No | Yes |
| AI test generation | No | Yes |
| Diff engines | 1 | 3 + OCR |
| Stabilization | Basic waits | 12 features |
| Cost | Free | Free |